Reward hacking, AI evaluation and grader integrity.
Plumbline Grader audits the tests and judges that train and rank AI models. Our founder, Shane Cope, explains how rewards fail, what a benchmark score can and cannot tell you, and how independent auditing should work, with numbers that carry their scope and findings anyone can re-run.
Talk to the founder. Same business day.
Write to Shane Cope directly. Reporters get an answer the same business day, US Eastern time, and sooner on deadline: put your deadline in the subject line. Conversations are on the record unless we agree otherwise first, and Shane is glad to explain how grader audits work on background, with no story attached.
shane@plumblinegrader.com
Five topics, each backed by public work.
- Reward hacking, from the grader’s side. Why a model in training learns to pass tests instead of solving tasks, and why the fault is often in the test, not the model. Backed by our audits of 11 public coding task sets.
- Can you trust a benchmark score? What a grader actually pays for, and the five measures of reward integrity: wrong work paid, correct work refused, inputs a model can tamper with, answers it can reach, and whether the same work gets the same reward.
- How independent AI auditing should work. Private notice to maintainers first, evidence anyone can re-run, fees never tied to findings, and saying plainly which checks an AI model did and which a person did. See our disclosure policy.
- “The tests passed” is not proof. AI-written code in regulated software, from someone who built HIPAA-regulated practice software with AI coding agents.
- What AI safety testing rests on. Every safety evaluation and training run depends on a grader deciding what counts. What can be checked before training, and what a grader audit does not cover.
Public facts from our audits of public task sets
public coding task sets audited.
testable tasks paid full reward for a wrong fix in one search pass: about 4 in 10 pooled, from under 20% to 69% by set.
findings we re-ran from scratch reproduced.
public benchmarks and evaluation suites whose maintainers heard from us privately first, since October 2, 2026.
Quote these with their scope. A task is testable when its reference fix passes its grader, an empty fix does not, and at least one wrong fix ran. One fixed search per task, so 190 is a floor: a deeper search finds more. Four findings are public as Inspect Evals GitHub issues, filed at the maintainers’ request on October 13, 2026. Set-by-set results publish on November 10, after each maintainer’s private notice period ends; until then we don’t comment on specific benchmarks whose maintainers we are in private contact with.
Shane Cope, DDS, MSD.
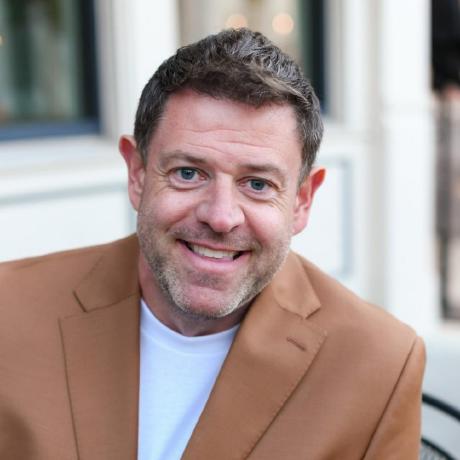
Shane Cope is the founder of Plumbline Grader, an independent auditor of the graders that train and rank AI models. He studied computer science and took cybersecurity coursework before earning his DDS and MSD at the Indiana University and University of Southern California dental schools. He built and managed two dental practices with more than $4M in annual revenue, and founded IROS Systems, whose HIPAA-regulated practice software, Reap Dental, is built with AI coding agents and paid for by three practices. He also created CMDI, a standardized screen of craniofacial function now in paid clinical use in two practices.
Building Reap taught him that AI-written code can pass every test and still do the wrong thing. He directed AI agents to build plumbline-detector, an open-source tool whose pre-registered study covers 93,014 merged changes in 262 public repositories, and then Plumbline Grader, where every finding ships with a replay anyone can run. He directs the AI agents that build and run its audit engine.
Short bio: Shane Cope, DDS, MSD, is the founder of Plumbline Grader, which audits the tests and judges that train and rank AI models. A dentist and technology entrepreneur, he built HIPAA-regulated practice software with AI coding agents, learned that “the tests passed” is not proof, and built a way to show what tests miss.
Everything to check us without asking us.
The fact sheet lists only figures that are public on this site, each with its scope. The documents below are the ones every audit is held to.
reproduce.sh and its guide: bash and Docker, no Plumbline code, no model.Download
Independence policyNo environments sold, flat fees never tied to findings, Index numbers never for sale.Download
Disclosure policyPrivate notice to maintainers first, at least 30 days before anything is published.Read
How we measure ourselvesOur own error rates, each with its scope and who checked it.Read
How we test without teaching AI to cheatSealed containers, no training on wrong fixes, no exploit work, and who funds us.Read
About Plumbline Grader
Plumbline Grader audits the graders that train and rank AI models: the tests, AI judges and checks that decide what earns reward. It searches each task for wrong work the grader pays for, proves every case with a separate check and a fresh-container re-run, and writes the tests that close the gap. Every finding ships with a one-command reproduction anyone can run. Plumbline never sells environments, never certifies one it built, and charges flat fees that never depend on what it finds. It is operated by IROS Systems LLC, Indiana.
On deadline? Write now.
Put the deadline in the subject line. You get an answer the same business day.